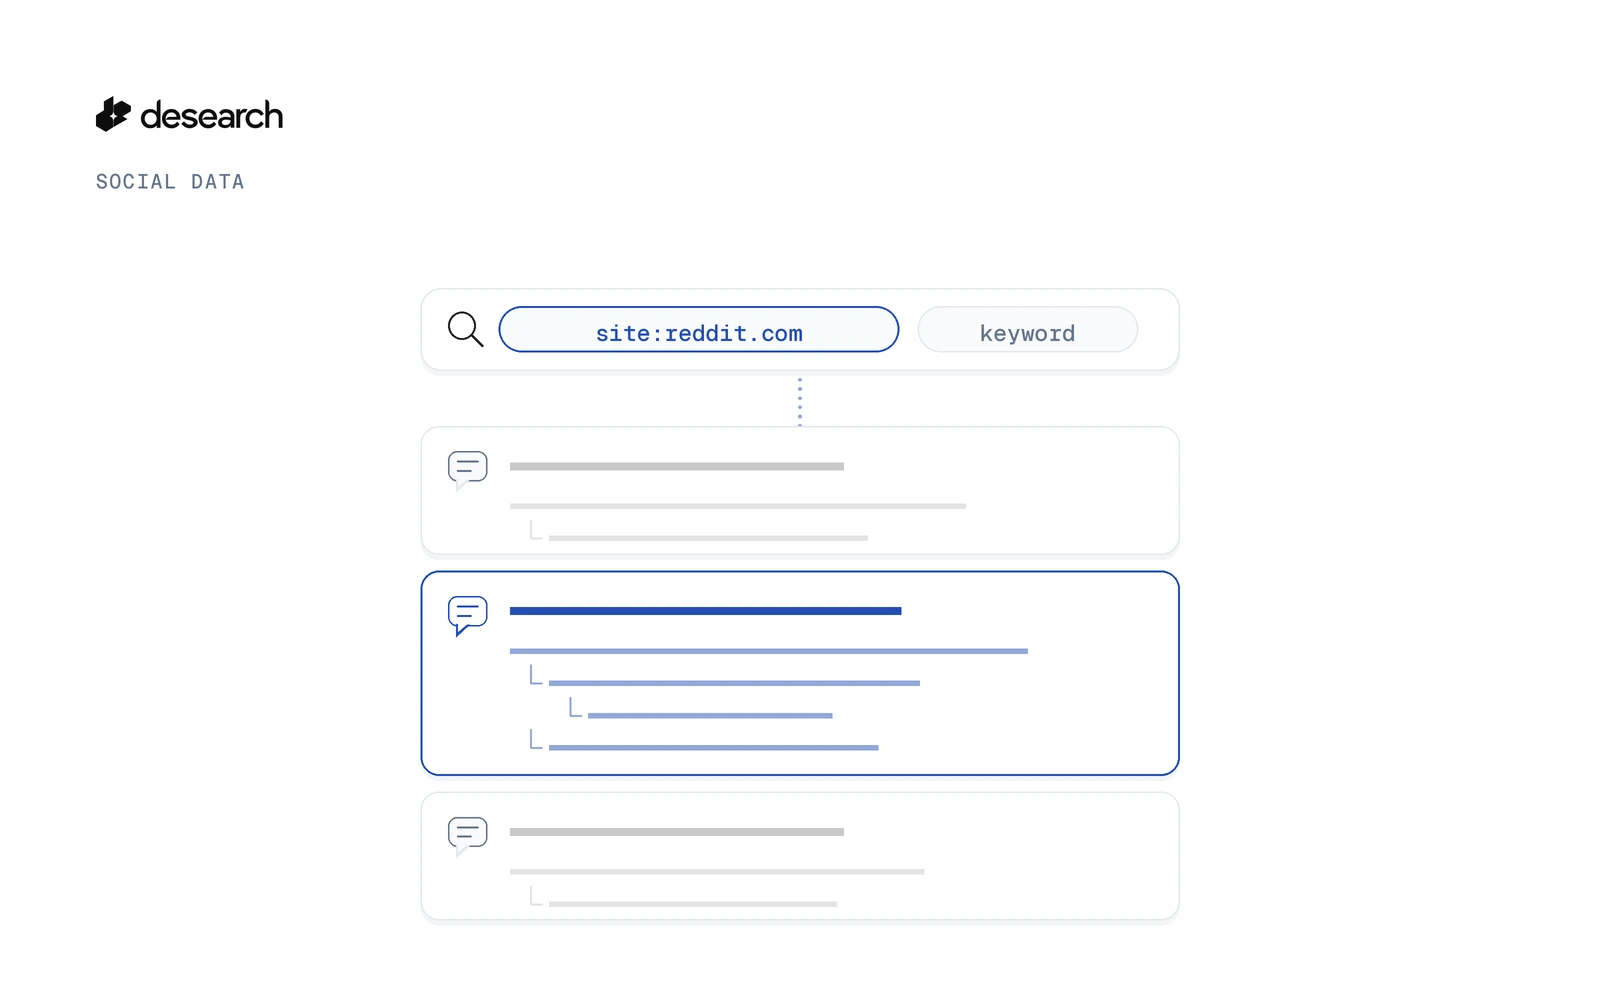
To find Reddit threads about a topic, send a keyword query with site:reddit.com to the Desearch Web Search endpoint, GET https://api.desearch.ai/web. You get back web results scoped to reddit.com, each with a title, a link and a snippet, up to 20 results per request. Raise start to get the next page. For the product overview, see the Reddit search API page.
This guide walks through the request in cURL and Python, shows how to page through results and keep only thread links, and covers the error codes you'll want to handle.
What you get back (and what you don't)
GET /web returns web results only. When you add site:reddit.com to the query, those results are Reddit pages that match your keywords. Each result gives you:
| Field | Use it for |
|---|---|
title | The thread title, as it appears in the result |
link | The URL of the Reddit page |
snippet | Short preview text. It can be empty, so don't rely on it |
This is web search scoped to one site. It doesn't go through the official Reddit API, and it doesn't return comments, votes or user data. If you need more than the title, link and snippet, open the link and read the page yourself.
Make your first request
Get an API key in Console
Create a key in Desearch Console. New accounts get $5 in API credits after attaching a card in Console, then pay as they go.
Request parameters
| Parameter | Required | What it does |
|---|---|---|
query | Yes | Your keywords plus site:reddit.com |
start | No | The result offset for paging. Leave it out, or send 0, for the first page |
Those are the only two parameters GET /web takes. The full schema is in the GET /web API reference.
cURL example
Put site:reddit.com anywhere in the query, next to your keywords:
curl --get 'https://api.desearch.ai/web' \
  --header "Authorization: $DESEARCH_API_KEY" \
  --data-urlencode 'query=site:reddit.com python web scraping' \
  --data-urlencode 'start=0'
The response is a JSON object with a data array of results. This shows the shape only, not a captured run:
{
  "data": [
    {
      "title": "Example thread title",
      "link": "https://www.reddit.com/r/example/comments/abc123/example_thread/",
      "snippet": "Short preview text."
    }
  ]
}
Python example
This version is written from the API schema with plain requests. It is not a captured run:
import os
import requests

resp = requests.get(
    "https://api.desearch.ai/web",
    headers={"Authorization": os.environ["DESEARCH_API_KEY"]},
    params={"query": "site:reddit.com python web scraping", "start": 0},
    timeout=60,
)
resp.raise_for_status()

for item in resp.json().get("data", []):
    print(item.get("title"))
    print(item.get("link"))
    print(item.get("snippet") or "(no snippet)")
    print()
Use .get() for every field so a missing or empty value doesn't break the loop.
Page through results with start
Each request returns up to 20 results. To get more, send the same query again with a higher start offset. The simplest rule is to move start forward by the number of results you just got.
You can send any offset. When there's nothing left, for example when start is past the last result, the API returns 503. A search with no results is not charged, so a 503 is a safe signal to stop.
This loop is written from the API schema, not a captured run. It collects up to max_pages pages and stops early on a 503 or an empty page:
import os
import requests

URL = "https://api.desearch.ai/web"
HEADERS = {"Authorization": os.environ["DESEARCH_API_KEY"]}


def find_reddit_results(keywords, max_pages=3):
    query = f"site:reddit.com {keywords}"
    results = []
    start = 0

    for _ in range(max_pages):
        resp = requests.get(
            URL,
            headers=HEADERS,
            params={"query": query, "start": start},
            timeout=60,
        )
        if resp.status_code == 503:
            break  # no more results, not charged
        resp.raise_for_status()

        page = resp.json().get("data", [])
        if not page:
            break
        results.extend(page)
        start += len(page)

    return results


results = find_reddit_results("python web scraping")
print(len(results))
Set max_pages to the number of pages you actually need. Each page is a separate request.
Keep only thread links
A site:reddit.com search can also return subreddit front pages, user pages and other Reddit URLs. If you only want discussion threads, keep links that contain /comments/, which is the path Reddit uses for thread pages. Drop repeated links at the same time:
def reddit_threads(results):
    seen = set()
    threads = []
    for item in results:
        link = item.get("link") or ""
        if "/comments/" not in link or link in seen:
            continue
        seen.add(link)
        threads.append(
            {
                "title": item.get("title") or "",
                "link": link,
                "snippet": item.get("snippet") or "",
            }
        )
    return threads


for t in reddit_threads(results):
    print(t["title"], t["link"])
This filter runs on your side, after the response comes back. The API returns whatever web results match the query. If a query returns 503, it found nothing, so loosen the keywords and try again.
Handle errors
| Status | What it means | Charged |
|---|---|---|
200 | Results came back in data | Yes |
422 | The query was empty or only whitespace | No |
503 | The search found no results, including a start past the last result | No |
Check that the query isn't blank before you send it. That avoids the 422. Treat a 503 as "no results here" rather than a failure worth retrying in a tight loop.
What it costs
Web Search: $1.00 / 1000 searches. Confirm current rates in Console.
Requests that return 422 or 503 are not charged. For how usage turns into billing, see the pricing page.
Where to go next
- For the general pattern of searching the web and then reading the pages you find, see search and extract web pages for AI agents.
- To turn Reddit searches into a list of leads, see Reddit lead generation in Python.
- To search other sites the same way, swap the domain in
site:. The Web Search API page covers the endpoint in general.
Reddit is not an AI Search tool. AI Search tools are web and X only, and you reach Reddit through GET /web with site:reddit.com.
FAQ
How do I search Reddit by keyword with an API?
Call GET https://api.desearch.ai/web with your keywords and site:reddit.com in query. Each result has a title, link and snippet.
How many results do I get per request?
Up to 20. Raise start to get the next page.
How do I get the next page?
Send the same query with a higher start offset. Moving it forward by the number of results you just got is the simplest rule. When start goes past the last result, you get a 503, which is not charged.
Does this return Reddit comments or votes?
No. GET /web returns web results only: title, link and snippet. It doesn't use the official Reddit API and doesn't return comment or vote data.
What happens if my query is empty?
An empty or whitespace-only query returns 422 and is not charged.
Is Reddit a source in AI Search?
No. AI Search tools are web and X only. For Reddit, use GET /web with site:reddit.com.
How much does it cost?
Web Search: $1.00 / 1000 searches. Confirm current rates in Console.
Get started
Get an API key in Console and run your first Reddit thread search. New accounts get $5 in API credits after attaching a card in Console, then pay as they go.
Reference: GET /web API reference